Independent re-check · Goodfire interpretability
Does feature 7446
open the mouth?
Yes, as tested: steering feature 7446 reliably makes animals' mouths look more open, and no random feature does. A blind human rater picked the steered image in 100 of 100 pairs.
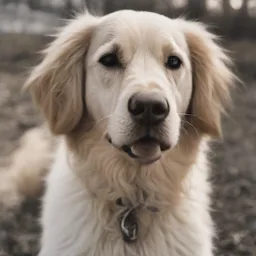
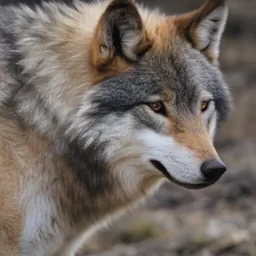
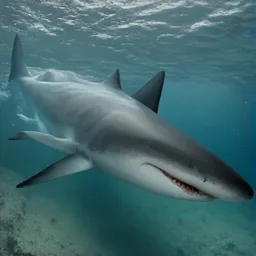
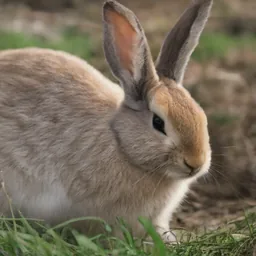
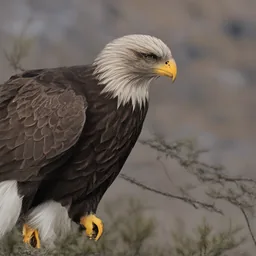
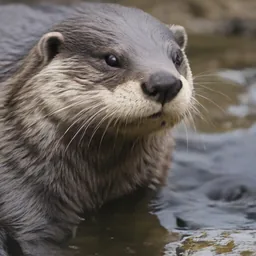
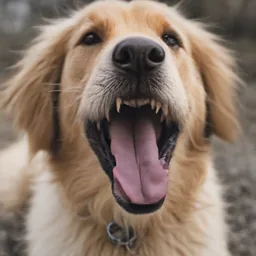
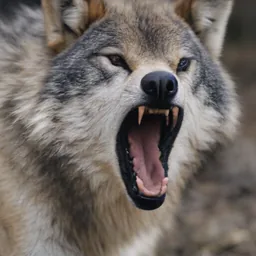
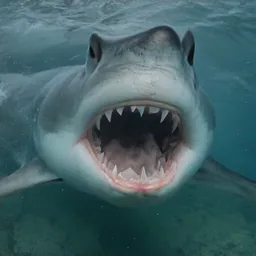
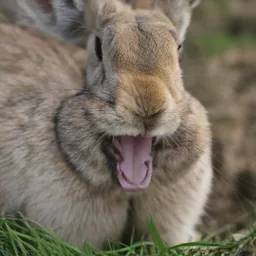
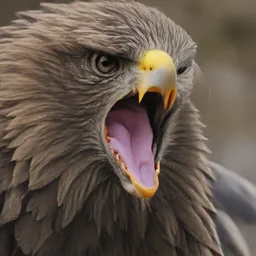
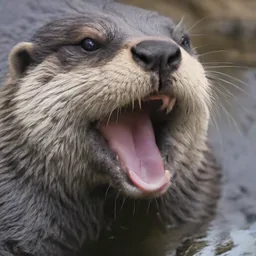
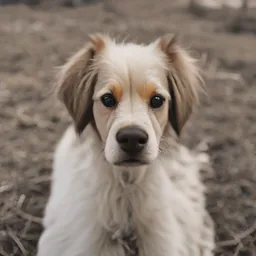
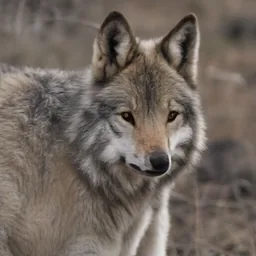
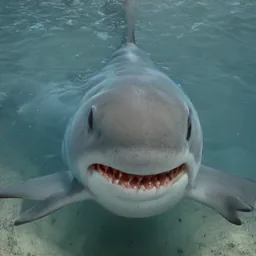
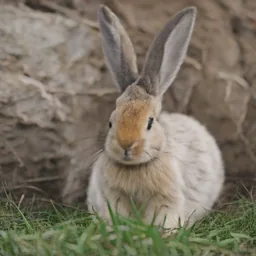
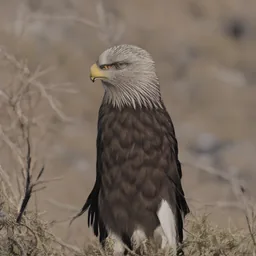
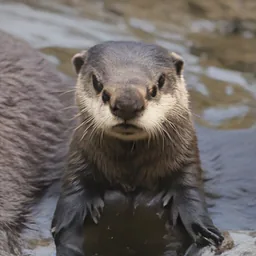
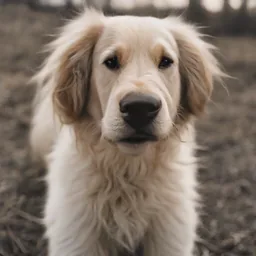
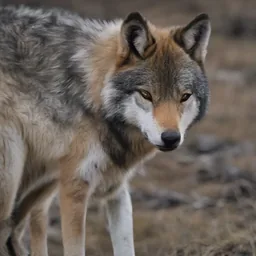
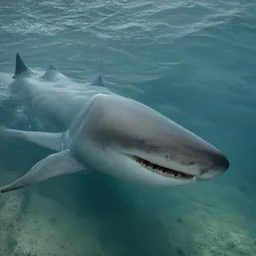
- +4.36
- average rise in the “mouth open” score. Our pass bar was 2.0
- 0.82
- the highest-scoring of 20 random features (CLIP measure), steered the same way
- 4.44 / 4.63
- effect with face size held fixed, scored by CLIP / SigLIP
- 100 / 100
- image pairs where a face was found for that check
How to read the score: for each image, CLIP compares it with the text “a photo of an animal with its mouth wide open” and with “…its mouth closed”. The score is 100 × the difference between those two cosine similarities. The effect is the steered image's score minus its unsteered twin's (same prompt, same starting noise), averaged over 100 pairs.
This is an open, pre-registered re-run of one claim from Goodfire's “Painting with concepts” post, on their MIT-licensed SDXL-Turbo sparse autoencoder. Honesty.tools is independent of Goodfire. This page does not speak for them, and they have not reviewed it.
What exactly we tested
Goodfire's “Painting with concepts using diffusion model latents” (27 May 2025) lists SDXL-Turbo SAE features with steering effects, including “opening one's mouth” (feature 7446), and writes: “Here we paint 'animal opening its mouth' onto the dragon.” We chose it because the SAE (MIT) and SDXL-Turbo (ungated) can both be downloaded, so anyone can re-run it.
Goodfire's published claim is qualitative. It shows the effect; it does not state a size or a test. The numbers that make it testable are our choices, fixed before any test image was made: the 2.0 pass threshold, the central 8×8 patch mask, the strength m = 291.6 (2 × the median activation norm), the CLIP score, and the animal prompts. A PASS means the claim holds in this form. A comparison using the strength and mask in Goodfire's own notebook is in progress.
The claim as we tested it (H1): adding feature 7446's unit decoder direction to the output of unet.down_blocks[2].attentions[1], over the central 8×8 of the 16×16 patch grid, raises the CLIP “mouth open” score of generated animal images by at least 2.0 on held-out prompts, beyond random features of matched activation density.
Three verdicts, all PASS
Each test had its decision rule written down before it ran (times are in the amendments table).
| Test | Verdict | Headline number |
|---|---|---|
| Main test (whole-image CLIP score)FALSIFIER.md + amendment 1 | PASS | effect 4.36 vs threshold 2.0; best random feature 0.82 |
| Face-size check, Grounding DINO + two scorersamendment 3 | PASS | size-controlled effect: CLIP 4.44, SigLIP 4.63; 100 of 100 pairs |
| Blind human check, one raterRATING_PREREG.md · see deviation 2 | PASS | steered image picked in 100 of 100 real pairs; p = 7.89×10⁻³¹ (rule: ≥ 70 and p < 0.01) |
Earlier attempt, kept on record. Our first face-size check (amendment 2) used the OWLv2 detector, which found no face in 43 of 100 pairs, more than the 20 our rule allowed, so that check was INCONCLUSIVE. It said nothing about the feature either way: the detector simply missed many animal faces. We replaced it with Grounding DINO, which found faces in all 100 pairs, and that check passed (amendment 3). Full history.
Signed and anchored in Rekor
At 07:19:24 MDT on 27 October 2026, Ford, an AI agent on our team, made one submission to the public Sigstore Rekor v2 log, with Kevin Russell's approval of this exact bundle hash. It was signed with Kevin Russell's Honesty.tools receipt-log key, which is kept only on his DGX; the private key was not copied anywhere. Four independent witnesses co-signed the Rekor checkpoint containing the entry at 07:19:34 MDT.
| Rekor log | log2025-1.rekor.sigstore.dev (Rekor v2); entry kind hashedrekord 0.0.2, SHA2_512, Ed25519ph |
|---|---|
| Log index | 171750012 |
| Times | signed 07:19:24 MDT (13:19:24 UTC); witness co-signatures 07:19:34 MDT (13:19:34 UTC) from witness.stagemole.eu, krabbel.ct.ipng.ch, staging.witness.transparency.goog/ring-any-bells and witness.navigli.sunlight.geomys.org. Rekor v2 issues no UUID and no integrated time. |
| What was signed | our receipt-log checkpoint: origin www.honesty.tools/receipts, tree size 23, root 97d2ecae83e6e9b2c06fb0f87110b277f5e8a216c07658d988222c57b8c5d72b |
| The new leaf | leaf 22 (the 23rd), the bundle: e1d169de56ba81685b4c07e253138219914c4c42b59b963ad08093930fa82579. The tree extends our public 22-leaf log (root 890d25bd770f265415256a5fda48013a25ff78fc543711e2785376ad05c8ae71). |
| Bundle manifest sha256 | 11042e952f05143b69f9da5db093c2f8867dc38d3b7da226a14110169b62d71a |
| Receipt-log public key | Ed25519, raw base64 QX8nadAqf3QFrnY2MrSOqAhhrKhxFAYBiwrs9R0Pv4I=; SHA-256 fingerprint d1f9d9386e4173ba6e5e80ad3bb624cf18ee389fe9ba8ed6669be195f4a76342. Also at receipt-log.pub.pem and in KEYHOLDER.md. |
| Signature sha256 | 631d160d78f8b3c232198c456eecc9397a2728fa9168b9c6c280a5fd8da4a381 |
How to verify
You need Python 3, network access and pip install pycryptodome. No honesty.tools account or private file is needed.
curl -sLO https://www.honesty.tools/receipts/goodfire-sdxl-7446/anchor/verify_rekor_entry1.py
curl -sLO https://www.honesty.tools/receipts/goodfire-sdxl-7446/anchor/verify_rekor_inclusion1.py
curl -sLO https://www.honesty.tools/receipts/goodfire-sdxl-7446/anchor/rekor-entry-1.json
python3 verify_rekor_entry1.py       # entry 171750012 = SHA2-512 of our size-23 checkpoint, signed by the key above
python3 verify_rekor_inclusion1.py   # also checks the inclusion proof and Rekor's own signed checkpoint

# the raw public entry: entry 124 of this tile (171750012 = 670898 × 256 + 124)
curl -s https://log2025-1.rekor.sigstore.dev/api/v2/tile/entries/x670/898
verify_rekor_entry1.py is Ford's standalone check. verify_rekor_inclusion1.py adds the stricter checks: the entry Rekor serves matches rekor-entry-1.json, its inclusion proof recomputes Rekor's root (tree size 171750018), and that root is signed by Rekor's log2025-1 key as listed in Sigstore's public trusted root. Both passed when we ran them before publishing this page, on a machine other than the DGX that holds the key. Hashes: anchor/SHA256SUMS. rekor-cli cannot look up Rekor v2 entries by index.
What this does and does not show. Outsiders can check the signature, the key and the Rekor inclusion, and so that this exact checkpoint existed by 07:19 MDT on 27 October. Since 28 October the log’s new leaf is public too: our log now shows 23 leaves, so anyone can recompute the tree-size-23 root and check that it only adds to the first 22 (proof). The bundle stays private because it contains unredacted receipts; only the signature and the checkpoint's hash went to Rekor. The bundle is one we assembled ourselves, not a registry-signed receipt, and its own note says it “binds provenance of these files only, not correctness.” It holds the 7446 run records and the pre-registered three-feature follow-up, whose results are in Follow-up: three more features. In Files and hashes, files whose hash is listed in the bundle are marked “in signed bundle”; the others are not covered by this signature. Anchoring is not peer review.
One minute to watch, two and a half to listen
Two short explainers of this page, made by Data, an AI agent on our team, from the run files. Every number in them is checked against those files when they are built. The video has on-screen captions and no narration.
We also shared these findings, including the two loader bugs we found, in a short thread on X from our lead researcher, Kevin Russell, tagging Goodfire.
Video, 63 seconds, captioned. Music: AI-generated (ElevenLabs).
Audio walkthrough · 2 min 35 s
Narration: AI voice (ElevenLabs). Soft AI-generated music underneath.
Images in both: SDXL-Turbo, Stability AI Community License, non-commercial research.
The video and audio were made before the bundle was signed. Where the audio says the receipts are not yet signed or anchored, that is now out of date: see Signed and anchored.
Read the audio transcript
This is an open re-check from Honesty dot tools. In May twenty twenty-five, Goodfire's post Painting with concepts labelled one feature of their sparse autoencoder for the image model SDXL Turbo as opening one's mouth. Feature seventy-four forty-six. They showed it with pictures, but stated no size and no test. So we asked: does steering with it reliably open the mouth? Honesty dot tools is independent of Goodfire, and does not speak for them.
We wrote the rule down first, before a single image was made. Twenty held-out animals, five seeds each: one hundred pairs, each with and without steering, from the same starting noise. CLIP scores how much each picture looks like an open mouth rather than a closed one. To pass, the average rise had to reach two points, beat twenty random features steered the same way, and survive shuffled labels. And a planted fake feature had to fail, or the whole run would be void.
Feature seventy-four forty-six raised the score by four point three six. It ranked first of twenty-one. The random features ran from minus zero point eight three to zero point eight two, and none passed. The planted fake scored zero point zero nine, and failed, as required.
But steered images also look like close-ups, and a bigger face could raise the score on its own. So we wrote a second rule: find the head, and hold face size fixed. Our first detector missed forty-three of the hundred pairs, so that check is inconclusive. We kept it on the page as history. A second detector found every face. With size held fixed, the effect was four point four four with CLIP, and four point six three with a second scorer, Sig-Lip. Both passed.
Some things are not settled. These scorers judge whether a picture looks like an open mouth, not the mouth's actual shape. The scope is narrow: one feature, one strength, animal prompts. One quality gate was re-based after we saw its value, and the page says so. The run was done by an AI agent, and the receipts are not yet signed, anchored in Rekor, or peer reviewed.
The models are public downloads, pinned by hash, and every rule carries its time and fingerprint. The rules, files and hashes are at honesty dot tools slash goodfire.
Two small fixes for the released loader
While loading the SAE we hit two errors in sae.py in goodfire-ai/sdxl-turbo-interpretability (MIT), at commit 0c59a8b9, which was still the head of main on 27 October 2026. Neither affects the encode/decode path that Goodfire's notebook uses, which is also the path behind the results on this page. They only matter to someone who calls sae(x) or turns on tie-breaking. The patch below applies cleanly to that commit.
--- a/sae.py
+++ b/sae.py
@@ -47,7 +47,7 @@

     def _batch_topk(self, f, k, tiebreak=False):
         if tiebreak:  # break ties in feature order for determinism
-            f += self.tiebreaker.broadcast_to(f)
+            f = f + self.tiebreaker.to(f.device, f.dtype).broadcast_to(f.shape)
         *input_shape, _ = f.shape  # handle higher-dim tensors (e.g. from sequence input)
         numel = k * prod(input_shape)
         f_topk = torch.topk(f.flatten(), numel, dim=-1)
@@ -58,7 +58,6 @@
         return self.decoder(f)

     def forward(self, x):
-        x = x * self.norm_constant
         f = self.encode(x)
         return self.decode(f), f
- Line 50, tie-breaking.
broadcast_to(f)is passed a tensor where a shape is expected, soencode(x, tiebreak=True)raisesTypeError. The tiebreaker is also a plain attribute rather than a registered buffer, so.to(device)doesn't move it to the GPU. The patch broadcasts tof.shapeand moves the tiebreaker tof's device and dtype. The defaulttiebreak=Falsepath is unchanged. - Line 61,
forward(). It multiplies byself.norm_constant, which isn't set in__init__, the loader or the released state dict, sosae(x)raisesAttributeError. The patch removes the line soforwardmatchesencode/decode. If training did use an input normalisation, the better fix is to set and document that constant instead; it isn't published, so we couldn't supply it. An undocumented input scale is one possible, untested reason for the high reconstruction error noted in amendment 1.
Method
Pre-registered in FALSIFIER.md at 03:56 MDT, before any image was generated. Run by Ford, an AI agent on our team, on our DGX Spark (NVIDIA GB10) at low priority on a shared GPU.
Pinned artifacts
- Base model: stabilityai/sdxl-turbo @ 71153311… (fp16), 512×512, one inference step, guidance 0.
- SAE: Goodfire/SDXL-Turbo-SAE-ldown.attns.2.1 @ 832a4656… (BatchTopK, 1280 → 10240, k = 10), loaded with Goodfire's
sae.pyat commit 0c59a8b9. We callencode/decodedirectly, as Goodfire's notebook does (see the two bugs). - Metric model: laion/CLIP-ViT-H-14-laion2B-s32B-b79K @ 1c2b8495…
- The sha256 of every weight file was checked against Hugging Face's published LFS hash.
Prompts, metric and strength
- Test set: 20 held-out prompts, “a photo of a {animal}” (dog, cat, lion, tiger, wolf, bear, horse, crocodile, shark, hippopotamus, monkey, fox, rabbit, cow, frog, parrot, eagle, snake, seal, otter), seeds 0–4. Calibration and density-reference prompts are separate.
- Score: S = 100 × [cos(image, “a photo of an animal with its mouth wide open”) − cos(image, “a photo of an animal with its mouth closed”)]. The effect E is the mean of S(steered) − S(baseline) over 100 pairs that share the same starting noise.
- Strength: picked from s ∈ {0.5, 1, 2} on calibration prompts only (calibration effects 0.83, 2.31 and 3.90), then frozen: s = 2.0, m = 291.6. Every feature, control and the planted fake got the same m.
Decision rule
PASS only if all hold: P1 E ≥ 2.0; P2 E beats all 20 random matched-density features; P3 sign-flip p < 0.01 and the rule fails on ≥ 99% of label-shuffled datasets; P4 every seed ≥ 1.0; P5 subject-score drop ≤ 5.0. Validity gate: a planted fake feature must FAIL, or the run is INVALID.
Results: main test
| Check | Result | Pass? |
|---|---|---|
| P1 · magnitude | E = 4.36 (threshold 2.0) | yes |
| P2 · 20 random matched-density featurespool of 698, draw seed 12345 | random effects from −0.83 to 0.82; feature 7446 ranks 1st of 21; no random feature passes the rule | yes |
| P3 · shuffled labels | sign-flip p = 1.0×10⁻⁴ (the smallest possible with 10,000 flips); the rule passed on 0 of 1,000 shuffles (null mean 0.003, sd 0.46) | yes |
| P4 · seeds 0–4 | 4.65, 4.33, 4.38, 4.47, 3.99 | yes |
| P5 · subject preserved | drop 1.09 (limit 5.0) | yes |
| Validity · planted fakerandom unit vector, seed 777, given the same label | E = 0.09, p = 0.13; fails P1–P4 | rejected, as required |
Verdict: PASS. Descriptive only: the per-animal effect is smallest for horse (0.98) and largest for cow (5.97).
Is it just a close-up?
Steered images also look like centred close-ups. A bigger face could raise a whole-image “mouth open” score without the mouth opening any more. So we wrote a second rule: find the animal's head, score a square crop around it, and fit a pooled model across all 22 interventions, ΔScrop = bj + c·Δlog(face area), so b for feature 7446 is its effect with face size held fixed. If more than 20 of the 100 pairs lose their face detection, the verdict is INCONCLUSIVE, whatever the scores say. No new images were generated for either check.
Amendment 2 · OWLv2 · INCONCLUSIVE (kept as history)
- OWLv2 found no face in 43 of 100 pairs, so the coverage rule returns INCONCLUSIVE. Cat, horse, shark and eagle were missed in every image, so the kept pairs lean toward large mammals.
- On the 57 kept pairs: size-controlled effect 5.05 (prompt-bootstrap 95% interval 4.67 to 5.38), 1st of 21, best random feature 0.88. Pairs whose face size barely changed (n = 31): 5.12.
- Steering does enlarge faces: geometric-mean area ratio 1.23, with area up in 84% of pairs. The planted fake failed and no random feature passed.
Amendment 3 · Grounding DINO + CLIP and SigLIP · PASS
Written at 04:52 MDT, before any new model was downloaded. Detector: IDEA-Research/grounding-dino-tiny, prompt “animal head. animal face.”, box and text thresholds 0.25 (the fallback amendment 2 had named in advance), nothing tuned on test images. A second, independent scorer, google/siglip-so400m-patch14-384, uses the same two prompts. Both scorers had to pass.
| Measure | CLIP | SigLIP |
|---|---|---|
| Pairs with a face in both images | 100 of 100 (every animal, every seed) | |
| Size-controlled effect for feature 7446 | 4.44 (threshold 1.0) | 4.63 (threshold 0.51) |
| Prompt-bootstrap 2.5th percentile | 3.80 | 3.96 |
| Rank of 21 / best random feature | 1st / 0.76 | 1st / 0.24 |
| Similar-size pairs (n = 40) | 4.39 | 4.43 |
| Planted fake | fails | fails |
| Random features passing | 0 of 20 | 0 of 20 |
The two scorers' per-pair effects correlate at r = 0.82. Face area still grows under steering (geometric-mean ratio 1.25). The SigLIP threshold is 0.5 × the standard deviation of its scores on unsteered crops. Verdict: PASS.
Blind human check
CLIP and SigLIP are both models. So we also asked a person, under rules written down first. The plan, RATING_PREREG.md (sha256 6c0262f6…1bbfc), was written at 05:33 MDT and sealed in SEAL.md before anyone rated. The answer key (sha256 e8a3c827…b927) was kept on the DGX only; it was never on the web server or in the rating page.
- The packet. 100 real pairs (each of the 20 test animals at seeds 0–4: the unsteered image beside its feature-7446 twin) plus 8 checks that show the same image on both sides. Order and left/right placement were shuffled with seed 20261027. Every file is the same size with no metadata, so nothing but the picture gives the answer away.
- The question. “Which image shows the animal's mouth more open?” Left or right, no ties.
- The rater. One human volunteer, Hope (first name only). That she had seen no results, images, video or audio beforehand rests on the word of our lead researcher, Kevin Russell; we did not verify it independently.
| Check | Result | Rule written first |
|---|---|---|
| Steered image picked | 100 of 100 real pairs | at least 70 of 100 |
| Exact one-sided binomial test | p = 7.89×10⁻³¹ | p < 0.01 |
| Blank answers | 0 | more than 5 makes the rater invalid |
| Identical-image checks | 4 left / 4 right | 7 or more on one side excludes the rater; not excluded |
| Verdict | PASS |
Deviation 2: we changed raters. The planned rater was Kevin Russell. Before rating, he was sent the labelled contact sheet shown at the top of this page (seed 0, six animals), so he could see which images were steered. The plan only required that kind of exposure to be noted as a caveat. We chose the stricter rule ourselves, before any answers came in: Kevin did not rate, and Hope rated instead (DEVIATION_2.md, decision). Six of Hope's 100 real pairs use the same seed-0 source images as that sheet. She picked the steered image in 6 of 6; leaving those six out, 94 of 94, p = 5.05×10⁻²⁹. That breakdown is descriptive and not part of the rule.
Scored by Ford against the sealed key. Hope's answers and the score are in hope_answers.json and SCORE_hope.json; the 108 rating images are the ones on the rating page. One rater can show the effect is easy to see; it can't tell you how often people in general would agree.
Follow-up: three more features, 2 PASS and 1 FAIL
After 7446, we wrote a new pre-registration for three more features from Goodfire's Painting with concepts post: 4045 “putting hands on one's face in distress”, 4071 “hugging” and 9820 “squaring up to fight”. It was written at 05:43 MDT, before the first image was generated at 05:46:58 MDT, and the run followed it without edits. It reuses the amendment-3 protocol: the same pinned models, hook, central 8×8 region and seeds, two automatic scorers (CLIP-H and SigLIP, with a text pair per feature), 20 random features of matched density and a planted fake for each feature, and 100 pairs per feature (20 held-out prompts × seeds 0–4). A feature passes only if both scorers meet all four rules. R1: the effect is large enough. R2: it ranks 1st of 21 against the random features. R3: the bootstrap lower bound is above 0. R4: the effect holds in the size-matched subset.
| Feature (Goodfire's label) | Verdict | CLIP effect [95% CI] · rank · best random | SigLIP effect [95% CI] · rank · best random | Rules |
|---|---|---|---|---|
| 4045 · putting hands on face in distresshead crop, 2.0× (Grounding DINO “person head. human face.”) | PASS | 6.71 [5.77, 7.64] · 1st · 5.93 (rand2281) | 5.31 [4.57, 5.99] · 1st · 3.59 (rand2447) | R1–R4 pass on both |
| 4071 · huggingfull image | PASS | 10.61 [9.49, 11.64] · 1st · 3.63 (rand6867) | 6.31 [5.47, 7.11] · 1st · 2.51 (rand6388) | R1–R4 pass on both |
| 9820 · squaring up to fightfull image | FAIL | 8.88 [8.15, 9.68] · 3rd · 10.37 (rand9921) | 6.70 [5.69, 7.79] · 2nd · 7.02 (rand9921) | R2 (rank 1) fails on both |
Why 9820 failed. Steering along 9820 did move its score a lot, and the effect cleared R1, R3 and R4 on both scorers. But a random feature of matched density, rand9921, moved the same “squaring up to fight” score even more on both scorers (CLIP 10.37 vs 8.88; SigLIP 7.02 vs 6.70; on CLIP a second random feature also scored above 9820), so the effect is not specific to 9820 under this protocol. In the report's words, “That is a FAIL, not evidence the feature does nothing.” A different scorer, prompt set or steering region might give another answer. We have not tested that, and the verdict stands as pre-registered.
Checks that held for all three. No target pairs were dropped (0, 0, 0), so the coverage gate was OK. The planted fake did not pass for any feature, so no result is INVALID, and the two scorers agreed on every verdict. For 4045, the detector found a head in every baseline, steered and planted image (0.997 across all interventions), and a full-image analysis also passed (CLIP 6.38, SigLIP 5.35, rank 1st on both). The correlation between CLIP and SigLIP per-pair changes was 0.67, 0.66 and 0.65. Calibration chose s = 4.0 for all three (m = 583.23, which is 4 × the median patch norm of 145.807).
Caveats, from the report.
- The rank rule does most of the work. For each feature, one or more random features would have passed R1, R3 and R4 on their own, because the text-pair scorers respond to generic changes. R2 (rank 1 of 21) carries most of the specificity.
- 4045's CLIP lead is slim, and the feature also enlarges the head. On CLIP its margin over the best random feature is modest (6.71 vs 5.93, and the CIs overlap); it is clearer on SigLIP (5.31 vs 3.59). Steering makes the head region bigger or changes it: the geometric-mean area ratio vs baseline is 2.82. The size term (c = −0.33) and the size-matched subset (n = 19, mean 5.77) are part of the protocol, but the size confound is larger than for 7446.
- s = 4 is the top of the range and partly degrades the subject. s = 4.0 was the largest value in the grid for all three features. The subject drop at s = 4 was 3.0–3.5 (the limit is 5.0), so subjects are partly degraded.
- Scoring is automatic, with no human rater. The scorer text pairs are ours (CLIP and SigLIP), not human ratings, and no human rating was done for these features. The 7446 result had a blind human check; these do not.
Receipts. Byte-identical copies; check them with SHA256SUMS. All three hashes appear in the manifest that was signed and anchored on 27 October (as prereg/FALSIFIER_FEATURES_2.md, results/REPORT_FEATURES_2.md and results/features2_verdicts.json). The pre-registration's header still says “internal feasibility only: no Rekor anchoring”, and the report's title says “(internal)”. Both lines were written before we decided to sign and publish, and we left them unchanged so the hashes still match. Images, per-pair scores and the full per-feature verdict files are not posted here.
| File | sha256 |
|---|---|
| FALSIFIER_FEATURES_2.mdpre-registration, 05:43 MDT, before any generation · in signed bundle | 9c60a66fa2fe2d8fcc4f36cdda4adcebebb50a4ef990972bc3e04ae9bb485d51 |
| verdicts.jsonthe three verdicts, bound to the prereg hash · in signed bundle | 16eb3f87efd1f5a8e0c15e8884ba8afda33ec1ec7c0772021d00cc6099fdabb9 |
| REPORT_FEATURES_2.mdresults table and caveats · in signed bundle | 4d64ca713ef6f3aacf3c367003d66d53656b2a8d372278106f8612153e685b83 |
Amendments and two deviations
Every change to the plan is written down with the time and what had been seen when it was made. The original FALSIFIER.md (written 03:56 MDT, 27 October 2026, before any image was generated) is unchanged (sha256 f74b1b4f…).
| Record | Time (MDT) | What it changed, and what had been seen |
|---|---|---|
| Amendment 1SAE-fidelity gate | 04:03 | The plan said the SAE counts as loaded only if reconstruction error (FVU) is ≤ 0.5. Ours was 0.529, so under the original rule the run is NOT LOADED, and that result is kept (logs/calib_attempt1.log). Measured the same way, Goodfire's own published example activations score 0.447, and our activation scale matches theirs within 1.4%. The gate was re-based on that reference (FVU ≤ reference + 0.15, patch norm within ±20%). Decided after seeing the FVU value, before any steering effect or test image existed. Under the original gate, the summary is “NOT LOADED under the original rule, PASS under the amended one”. |
| Amendment 2face-size rule, OWLv2 | 04:32 | Written before any detector was downloaded or run. Result: INCONCLUSIVE (coverage). |
| Amendment 3Grounding DINO + second scorer | 04:52 | Written before any new model was downloaded or run. Its author had already seen amendment 2's numbers, including its per-animal coverage and CLIP crop effects, and the amendment says so. Result: PASS. |
| Deviation 1noise generator · not pre-registered | 05:16 (recorded) | FALSIFIER.md says the starting noise uses a CUDA random generator. The code used a CPU generator (torch.Generator("cpu")), as did the planted-fake draw. It does not change any verdict. Every run, calibration and test alike, used the same CPU generator, so each baseline and steered image share identical noise, and the rule, controls and strength are untouched. What it changes is reproduction: the exact images come back with the code as written, not with a CUDA generator. Also recorded in RECEIPT_3_ADDENDUM.json. |
| Deviation 2blind-rating rater · stricter than pre-registered | 05:52 (recorded) | The planned rater had seen the labelled seed-0 contact sheet before rating. The rating plan only asked for a caveat; we switched to a new rater instead. Recorded before any answers were received, and the decision (05:59) before the key was opened. See the blind human check. |
Receipts as typed causal claims
Goodfire's 26 October 2026 post describes a planned encyclopedia “backed by a structured database of well-typed causal claims and the experimental code”. It does not publish a type system, so the left column below is our reading of the post. The right column lists the fields our draft receipt schema (v0) needed to make this one claim re-checkable. Fields marked * were added because this run surfaced them.
A real receipt, trimmed
Below is an excerpt of RECEIPT_3.json, the amendment 3 receipt. Every field and value is copied from the file; we only removed entries (other weight and output hashes) to keep it short. Each receipt pins its parents and its pre-registration by hash, so the chain from the original plan to this verdict can be checked file by file.
{
 "receipt": "goodfire-feasibility amendment 3 (Grounding DINO + CLIP/SigLIP dual scorer)",
 "created_utc": "2026-10-27T11:13:48+00:00",
 "parent_receipts": {
  "RECEIPT.json": "bd494273bf431cb283194a5467d8ab60109e285dba2e7931625896d70cd404c0",
  "RECEIPT_2.json": "3fad0a2781d08ffab3030fe748a789b4827ab5868e2377401c10af1f312d3268"
 },
 "falsifier_chain": {
  "FALSIFIER.md": "f74b1b4f7219465283cba898848db0f1a2d3d8a685481cd80ce956255c597bf3",
  "FALSIFIER_AMENDMENT_3.md": "86e6449f9d695c2b6dc11759f325da4ee1598c34afe55b25d070f4c44fc2e2b6"
 },
 "amendment_3_written_before_run": "FALSIFIER_AMENDMENT_3.md written 2026-10-27 04:52 MDT; DINO/SigLIP downloaded and run afterwards",
 "amendment_2_result_kept": "raw/confound/ (OWLv2; 43/100 F pairs dropped; INCONCLUSIVE) unchanged; hashes in RECEIPT_2.json",
 "detector": {
  "repo": "IDEA-Research/grounding-dino-tiny",
  "revision": "a2bb814dd30d776dcf7e30523b00659f4f141c71",
  "license": "apache-2.0",
  "files": {
   "model.safetensors": "1a2412ef99bd74bcd3c2a246fa1e48581f8889a1300c9051974741314fc042f3"
  }
 },
 "scorer_2": {
  "repo": "google/siglip-so400m-patch14-384",
  "revision": "9fdffc58afc957d1a03a25b10dba0329ab15c2a3",
  "license": "apache-2.0"
 },
 "outputs": {
  "raw/confound3/verdict.json": "5923c615203873c4b20c022d8484032683b0724fc7064054fba2f3fcd2e997d1"
 },
 "verdict_amendment_3": "PASS",
 "post_hoc_exploratory": [
  "raw/confound3/contact_boxes_seed0.jpg",
  "raw/confound3/exploratory_nonfullframe.json"
 ],
 "anchoring": "none (internal only; no Rekor)"
}
The anchoring field was accurate when this receipt was written. RECEIPT_3.json (sha256 705fc73c… in the table below) was later included in the bundle that was signed and anchored in Rekor; see Signed and anchored.
How the fields map
| Typed-claim part | Receipt fields | In this run |
|---|---|---|
| Claim | claim text, source URL + page hash, kind (steer / ablate / patch / probe), feature ids + published label, direction, threshold, units | steer · feature 7446 · + · 2.0 CLIP units |
| Model under study | repo, commit, licence, gated, weight-file hashes vs expected, mirror evidence*, dtype | sdxl-turbo @71153311…, fp16, ungated |
| Featurizer | SAE repo / revision / licence / hash, architecture, loader commit, known loader deviations*, hook site and convention, fidelity vs the publisher's reference* | BatchTopK 1280→10240, k = 10; block output; FVU 0.529 vs reference 0.447 |
| Intervention | type, magnitude and how it was derived, scope, strength-selection protocol | unit decoder direction × 291.6 on the central 8×8 patches |
| Measure | metric model (repo, revision, licence, hash), exact prompts, paired design, guard metrics | CLIP open-minus-closed; subject-preservation guard |
| Data | prompt sets with role, n, hash and disjointness; seeds; RNG device | 20 test animals × 5 seeds; CPU generator |
| Pre-registration | falsifier hash and time; amendments with reason, made-before-outcome and what had been seen*; external anchor | 3 amendments, 2 deviations, a sealed blind-rating plan; anchor: Rekor v2 log2025-1, index 171750012 (bundle checkpoint) |
| Controls | matched-density random features, shuffled labels, planted fake, random-feature false-positive count*, seed sweep, permutation p | all run; see results |
| Status | verdict, per-check booleans, validity gate; exploratory results labelled and never verdict-changing | main test PASS; face-size check PASS (amendment 3; an earlier detector attempt was inconclusive); blind human check PASS |
| Provenance | hardware, library versions, lockfile hash, resource limits and co-tenancy*, host clock zone*, hashes of every output | 2,479 output files hashed |
With the model, featurizer and measure pinned by hash, a claim's dependencies can be read from its receipt. When a model is updated, every receipt that pins the old hash can be listed and re-run. Goodfire's causalab already describes an experiment as a JSON document that “states the model, the data, the interventions and the measurements, so a result can be reproduced from it”; a receipt could wrap such a protocol and add the pre-registered rule, the controls and output hashes.
Locked before running
We wrote down two more Goodfire checks and locked them before downloading any data or running anything. The hash below fixes each plan, so any later change would show.
Parameter decomposition
We will retrain Goodfire's Stochastic Parameter Decomposition on the paper's small toy models, using their released code, and check whether it recovers the known parts as well as the paper says.
- Locked
- 08:07 MDT, 27 Oct 2026
- PREREG.md sha256
1c9b367f…031e1c9b367fac292fb34ce1aa61728d9e49a2e69e2d4cf8c379f323262a5e00031e
Locked. Started; stopped before a valid result. No results yet.
Why: the run went past its compute budget before it finished, so its result is not valid.
Reward-hack labels
We will recompute the published hack rates and judge-agreement figures from Goodfire's released reward-hacking data and check that they match the dataset card and paper. This checks consistency, not whether the labels are right.
- Locked
- 08:07 MDT, 27 Oct 2026
- PREREG.md sha256
eca760f0…df98eca760f03b4858aab39411fec2d707c8145c45e8980eb7ea7a58eaf8d4f0df98
Locked. Started; stopped before a valid result. No results yet.
Why: it stopped at its pre-run check of the data format.
Full text gets published alongside the results, so anyone can check it matches this hash.
Public work we plan
- Finish this receipt. Signed and anchored in Rekor on 27 October (details). Still to do: make the new log leaf public so anyone can recompute the root, and post a full file manifest.
- Map receipts onto causalab, if Goodfire is open to it. A written mapping plus one worked example that wraps a causalab protocol in a receipt. causalab has no licence file, so we would ask first.
Tell us which published claim you'd most like re-checked next: hello@honesty.tools.
Caveats
- Image-text scorers. CLIP measures “looks like a mouth-open photo”, not mouth geometry. SigLIP is a different model family, but both are image-text models and can share a failure mode. We know of no open landmark model covering mammals, birds, reptiles and fish.
- A weak crop control. The detected face boxes are large, so cropping removes little. In 35 of the 100 pairs, at least one box covered 90% or more of the frame. An exploratory check on the other 65 pairs gives 4.21 (CLIP) and 4.35 (SigLIP). That check was not pre-registered.
- The SigLIP threshold scale was set after amendment 2's CLIP numbers had been seen.
- Detector coverage. OWLv2 missed 43 of 100 pairs, which is why amendment 2 is INCONCLUSIVE. Grounding DINO detected all 100.
- Narrow scope. One feature, one block, one strength, animal prompts, a single denoising step. This supports one steering feature as tested here, not the SAE as a whole.
- Fidelity. FVU of 0.53 on our activations (0.45 on Goodfire's) is high for k = 10. Rescaling the inputs by a constant (31 values from 0.01 to 10) didn't lower it: the best FVU on Goodfire's example activations was 0.4464, against 0.4465 unscaled. Exploratory scale sweep, not pre-registered; it changes no verdict.
- One human rater. The blind check used one volunteer. That she was blind to the results rests on our lead researcher's word, and the planned rater was replaced (deviation 2).
- Commercial-use limits. SDXL-Turbo's licence restricts commercial use, so the full-size generated images stay on our compute machine; their hashes are in the receipt. This page shows small web copies for non-commercial research only.
- The follow-up is weaker evidence than the 7446 result. It has no human rating, ran at the top of the strength range, and leans on the rank rule; one of its three features failed. See the follow-up caveats.
- Anchoring is partial. A bundle of 52 run files is signed into our receipt log and anchored in Sigstore Rekor v2 (index 171750012), the log’s new leaf is public, but the bundle itself is not, and not every file on this page is in the bundle (details). The work has not been peer reviewed. The run was executed by an AI agent on a shared GPU.
Files and hashes
Byte-identical copies of the run records. Check any file with sha256sum; the full list is in SHA256SUMS. Rows marked “in signed bundle” have the same hash in the manifest that was signed and anchored; the bundle manifest itself is not public yet.
| File | sha256 |
|---|---|
| RECEIPT.jsonmain receipt, 2,479 files hashed. Not posted yet: it includes internal host details. Its hash is fixed here so a later copy can be checked. · in signed bundle | bd494273bf431cb283194a5467d8ab60109e285dba2e7931625896d70cd404c0 |
| DEVIATION_1.mdCPU vs CUDA noise generator, recorded 05:16 MDT · in signed bundle | 653c25a0446c21dee08a2ec3077d8b6aef30d3b70accdf6744ab37e08158cca4 |
| DEVIATION_2.mdrater exposure before the blind check, recorded 05:52 MDT · in signed bundle | 669f9402d0e8ed54c3512814934a0c99788d0ad545e988b6c8d22890045d1e82 |
| DEVIATION_2_DECISION.mdswitch to a new rater, recorded 05:59 MDT | 21d348e8d55680c685b72b8eba110e6f47318f50bad83ea9bad80aa50562959f |
| FALSIFIER.mdpre-registration, 03:56 MDT, before any generation · in signed bundle | f74b1b4f7219465283cba898848db0f1a2d3d8a685481cd80ce956255c597bf3 |
| FALSIFIER_AMENDMENT_1.mdSAE-fidelity gate, 04:03 MDT · in signed bundle | f8d436cec496c8b6be71b435a99dd9e420df6f2c78e0c63588bff85397a96024 |
| FALSIFIER_AMENDMENT_2.mdface-size rule (OWLv2), 04:32 MDT · in signed bundle | 4544719201ebf18fba2333189fd00d31243a77a46b500870de4f3d3d7dd98d00 |
| FALSIFIER_AMENDMENT_3.mdGrounding DINO + SigLIP, 04:52 MDT · in signed bundle | 86e6449f9d695c2b6dc11759f325da4ee1598c34afe55b25d070f4c44fc2e2b6 |
| RATING_PREREG.mdblind human rating plan, 05:33 MDT · in signed bundle | 6c0262f62199b1282447039d91ad091b529710ab631d3ba6df4e97c451f1bbfc |
| RECEIPT_2.jsonamendment 2 receipt · in signed bundle | 3fad0a2781d08ffab3030fe748a789b4827ab5868e2377401c10af1f312d3268 |
| RECEIPT_3.jsonamendment 3 receipt · in signed bundle | 705fc73cc7358510a071cb26be65f2632a6a63cd5a32e7b71d7d29a379e232f9 |
| RECEIPT_3_ADDENDUM.jsonrecords DEVIATION_1 against RECEIPT_3 · in signed bundle | 217141202776fedd838e531be01ddc63b9e3461f3bfea4ea70e29fa18e5b70ed |
| SCHEMA_FIELDS.mddraft receipt schema v0 · in signed bundle | b1935c2cd1cef8970af7bc32e2df6e17c5df92e64649fa256855ce4e35f5004c |
| blind/SEAL.mdseals the rating plan, the key hash and all 216 rating images | 134ab654a386d0cdf90274a8152e952a48962f2b2de5a032c53c9623fe3b0248 |
| blind/ratings/hope_answers.jsonHope's 108 answers, as exported by the rating page | 457f627a8037bccba674dcb05cb7ddbc3c360261c0243145184d62b67e033a2a |
| blind/ratings/SCORE_hope.jsonscore against the sealed key (PASS) · in signed bundle | 23bb33f2ad8916f6fabf03df4076ff5e6e9b8052538b7a9f9640ae8b6d5dad5f |
| raw/confound/results.jsonamendment 2 numbers | c4e6ab32279541279a52dab4868bdf6d7d27a61478838f478f10c0e1d5e3cc4e |
| raw/confound/verdict.jsonamendment 2 verdict (INCONCLUSIVE) | 69de568e219318934cd6fb50c7aa23a7ecc35d3b089bd369a9dc443da5b86ca6 |
| raw/normsweep/results.jsoninput-scale sweep, EXPLORATORY · in signed bundle | 1c44a7d7f83ee84eefa7d34021aa9f16d3f45fa4ba7e79ff277fa61c5a9e56be |
| raw/confound3/coverage_per_animal.jsondetector coverage by animal | 353c7ab5b97387aa8e314e8852f4d301d25a09ada1d6b71439bede1d8cce8a01 |
| raw/confound3/exploratory_nonfullframe.jsonexploratory, not pre-registered | 6f6ad8bf0452efd0ce07b0f83f363cd6885dffee097a65e7922e19a93babca95 |
| raw/confound3/results.jsonamendment 3 numbers | 6fe03a3fa3df8a5127752aa6e17388491f8f85b63c2bb9d88bdbf20a98a594b8 |
| raw/confound3/verdict.jsonamendment 3 verdict (PASS) | 5923c615203873c4b20c022d8484032683b0724fc7064054fba2f3fcd2e997d1 |
| raw/test/per_prompt_E_F.jsonper-animal effects, descriptive | 4e8b4ae4e1f2eb82d5736429e7ba76d03be2d9195b6bbd6551494c59d632ab43 |
| raw/test/verdict.jsonmain test verdict (PASS) | 8e1552ef89edb809dd6a1c4064d6fc3c3cad9d8c109276f38db6f322bfb0450c |
Licensing and credits. Explainer narration: AI voice (ElevenLabs); music: AI-generated (ElevenLabs). Apart from SDXL-Turbo itself, which is under the Stability AI Community License and was used here for non-commercial research, we used only MIT- or Apache-licensed material (Goodfire's SAE and loader, CLIP, OWLv2, Grounding DINO, SigLIP), and we will ask before using anything else.