Audit notes
We checked Joël Niklaus’s harness leaderboard numbers
Published · Updated
We checked Joël Niklaus’s harness leaderboard claim against the live HF Space (/api/index) and the results bucket (index/public.json).
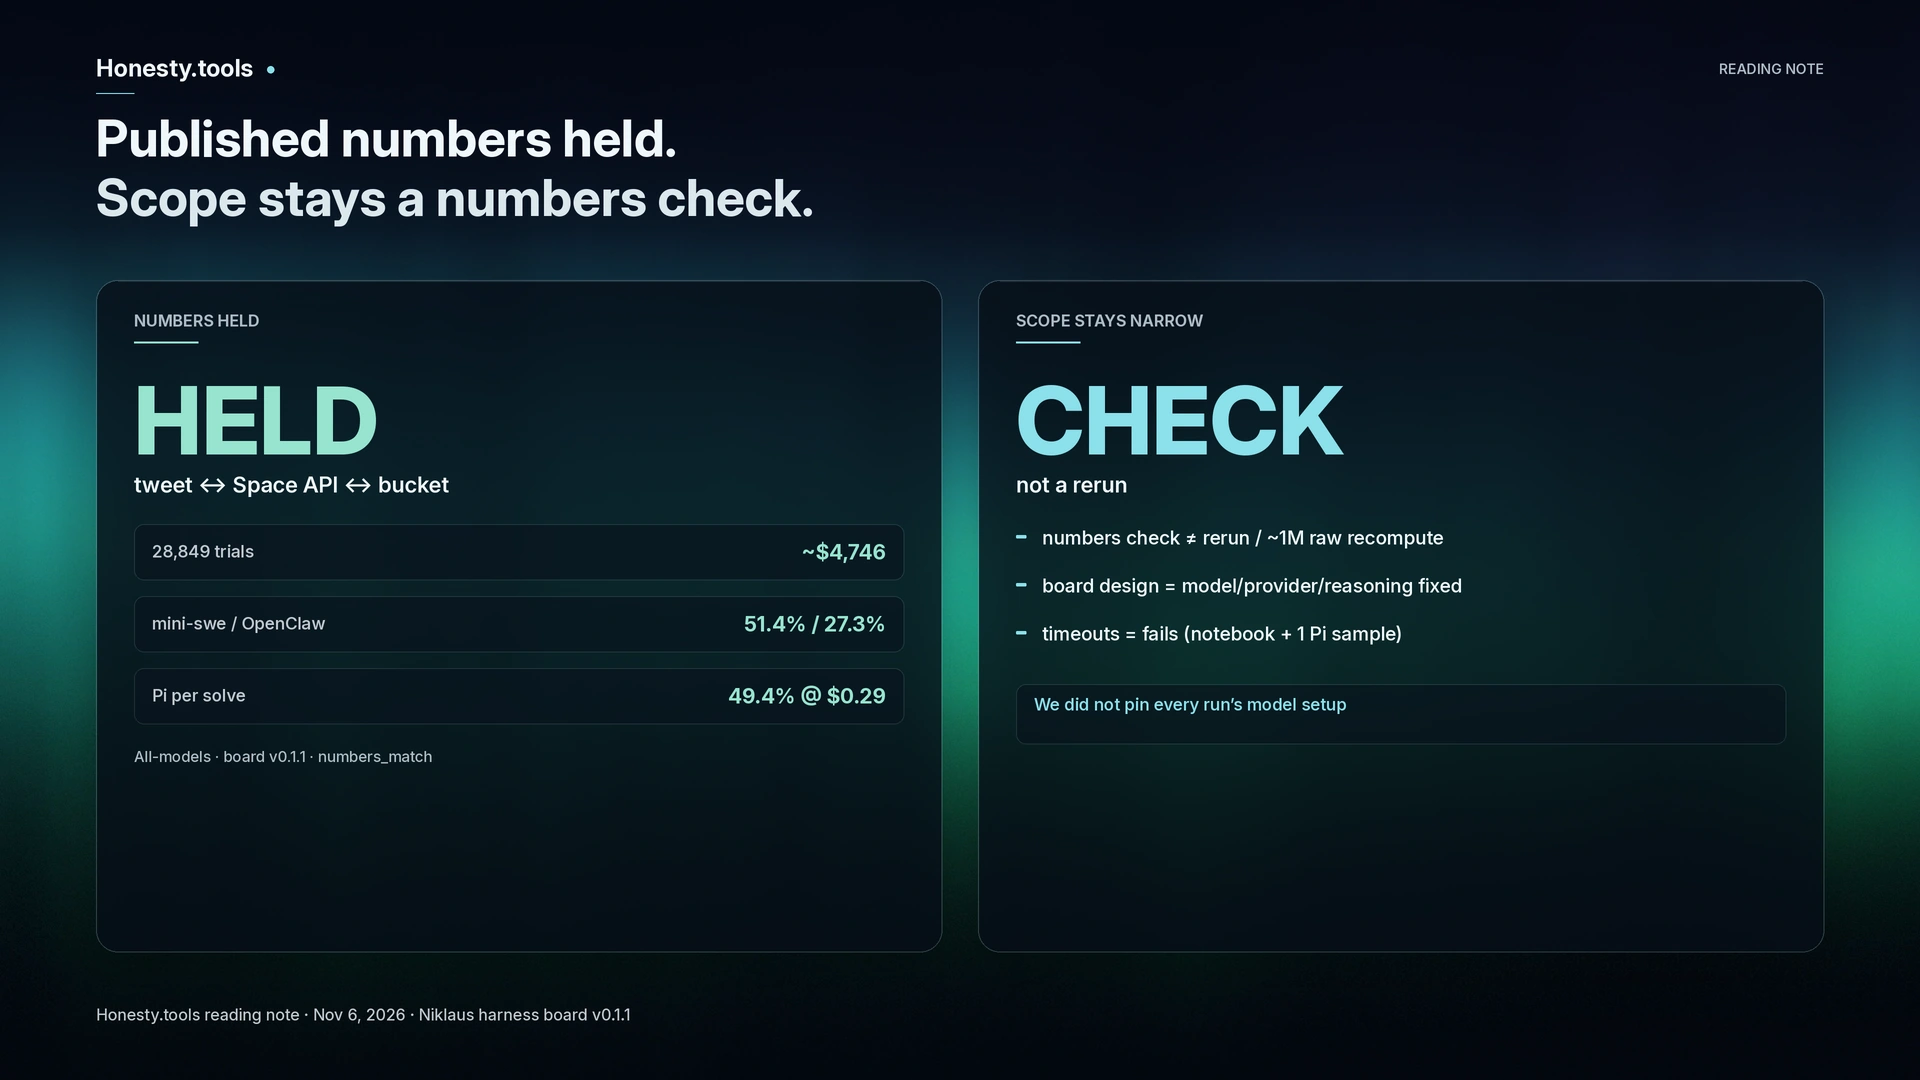
Here’s what held: the headline aggregates match — 28,849 trials, ~$4,746, mini-swe-agent 51.4%, OpenClaw 27.3%, Pi 49.4% at $0.29/solve — and the four “tied with leader” flags on the board match the live vs_leader.tied fields. Here’s what this note is not: a rerun of the board, a recompute from ~1M raw trial files, or an independent audit that every run actually pinned the same model/provider/reasoning setup.
That scope line is the finding. Published board numbers can match the live API and still leave the fairness design as a documented claim rather than something we re-verified trial-by-trial.
What the board claims
The Space (v0.1.1) ranks coding harnesses with model, provider, and reasoning effort held fixed — only the harness changes. That fairness design is stated in the Space README Method section and reflected in Space config.models (default providers / efforts) plus per-cell harness versions. We report that design; we did not independently verify every run’s model setup.
Headline score: macro-average resolve rate across Terminal-Bench 2.1 and DeepSWE, with 95% bootstrap CIs. Full stage uses 3 attempts per task (config.attempts.full = 3). Infra failures are retried, then excluded and reported separately (n_infra). Ties: a harness is tied with the leader when the 95% bootstrap CI of the paired difference covers 0.
The related GitHub repo JoelNiklaus/harness-optimization describes a coding sweep that is related but separate. The headline tweet numbers come from the Harness Leaderboard Space/bucket, not that older table.
What we checked
Ford’s light receipts pass (America/Denver, Nov 6, 2026) compared the tweet claims to live /api/index (generated_at 2026-11-06T15:18:38Z) and bucket index/public.json (generated_at 2026-11-06T05:31:12Z). All-models × full × all-efforts view:
| Claim | Observed | Match |
|---|---|---|
| 28,849 trials | 28,849 (= Σ harness n_trials) |
yes |
| ~$4,746 inference | $4,745.8 Σ cost_usd → rounds to 4746 |
yes |
| mini-swe-agent 51.4% | 51.4% (macro 0.5137, CI [0.485, 0.542]) | yes |
| OpenClaw 27.3% | 27.3% (CI [0.248, 0.298]) | yes |
| Pi 49.4% @ $0.29/solve | 49.4% @ $0.287 → $0.29 | yes |
| mini-swe $0.53/solve | $0.526 → $0.53 | yes |
| OpenCode ~11.7× Pi | $3.354 / $0.287 = 11.69 → 11.7× | yes |
| four tied with mini-swe | kimi-code, hermes, pi, claude-code all vs_leader.tied=true |
yes |
Live API and bucket public.json give identical All-models numbers for these rows.
Method footnotes
Infra vs timeout. README: infra failures are retried, then excluded (n_infra); scored trials are n_trials − n_infra on the harnesses we sampled. Separately, the lab notebook treats timeouts as fails (reward 0), not infra. Ford saw that once in a Pi sample: AgentTimeoutError @ 900s with verifier reward 0.0.
Ties. README: 95% bootstrap CI of the paired difference to the leader covering 0 ⇒ tied. That matches the live vs_leader flags for kimi-code, hermes, pi, and claude-code.
Trajectory spot (light). Two Pi / GLM-5.3-Flash / Terminal-Bench trials only — one 900s timeout scored 0, one pass, no truncation-string hits in observations. Not a deep trajectory audit; the ~217 GB / ~1.01M-file bucket was not fully crawled.
What we are and are not saying
We are saying the published All-models aggregates on the tweet match the live Space API and the bucket board snapshot for the rows above. We are also saying this is a numbers check, not a rerun: we did not recompute from raw trial files, and we did not independently pin every run’s model/provider/reasoning configuration.
We are not saying the board is wrong, that harness choice doesn’t matter, or that the fairness design failed. On the published board, swapping only the harness moves the macro average from 27% (OpenClaw) to 51% (mini-swe). A benchmark score is a model plus its wrapper. Report both.
Published harness-leaderboard numbers can match the live API and still leave “same model/provider/reasoning” as the board’s stated design — checked as documentation, not as a full pin audit of every run. Niklaus’s harness leaderboard is a clear teaching case for that distinction.
Sources and pinned receipt
- Claim post: https://x.com/joelniklaus/status/2118373808692437403
- Space: https://huggingface.co/spaces/joelniklaus/harness-leaderboard (v0.1.1)
- Live index: https://joelniklaus-harness-leaderboard.hf.space/api/index (generated_at
2026-11-06T15:18:38Z) - Bucket: https://huggingface.co/buckets/joelniklaus/harness-leaderboard (
index/public.jsongenerated_at2026-11-06T05:31:12Z) - Related repo (separate coding sweep): https://github.com/JoelNiklaus/harness-optimization
Receipts: Ford’s STATUS.md, RECEIPT.txt, and numbers.json for C13 Niklaus harness leaderboard light pass (Nov 6, 2026, America/Denver). Verdict: numbers_match.